Top-Down Parsing#
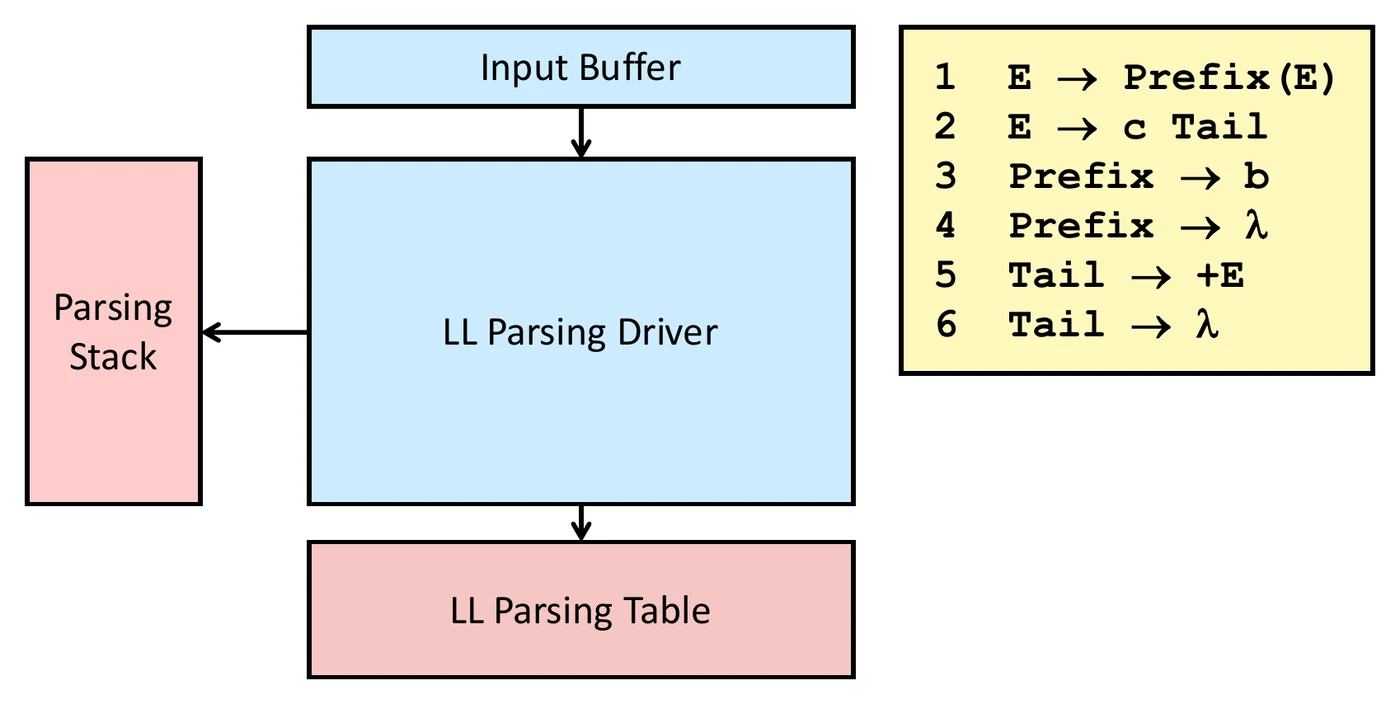
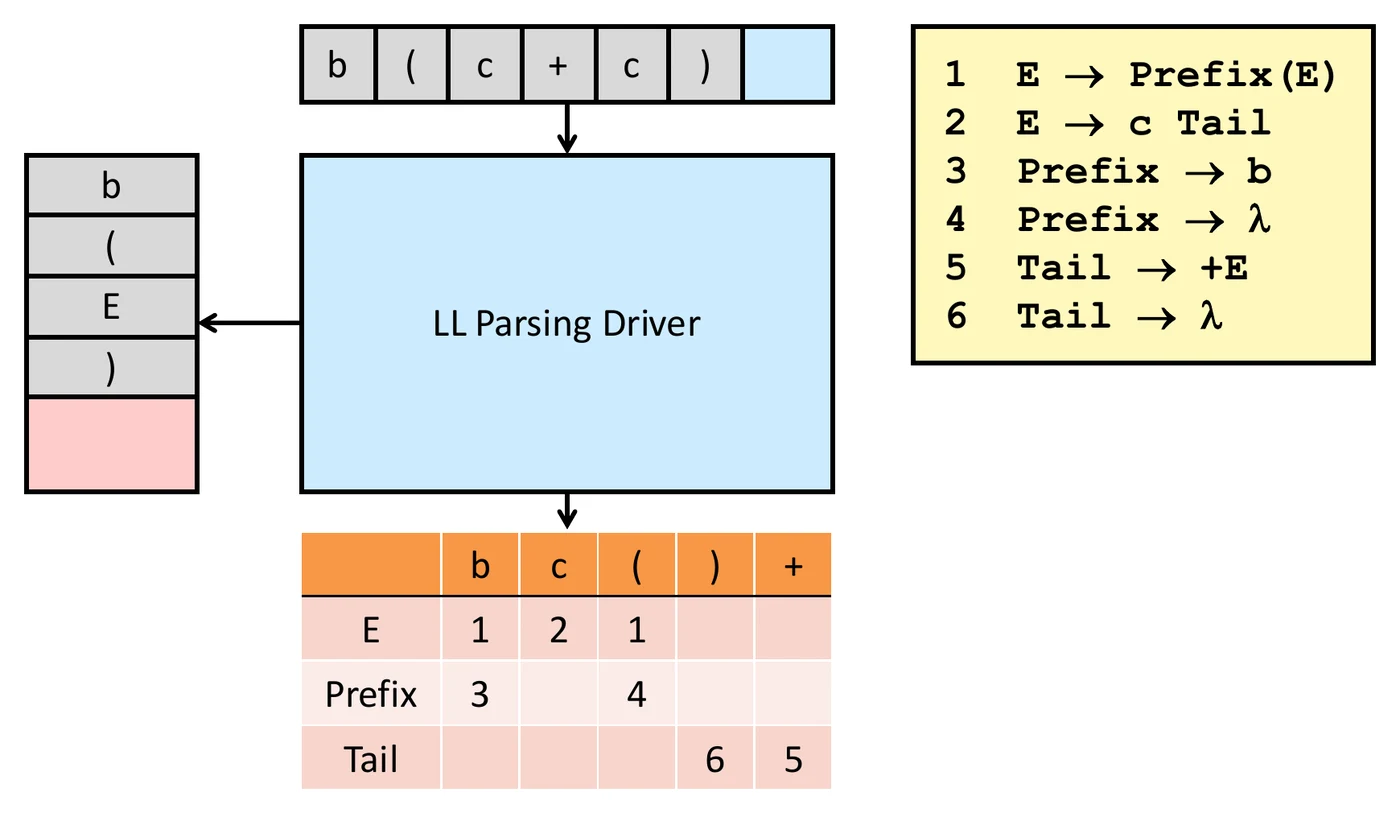
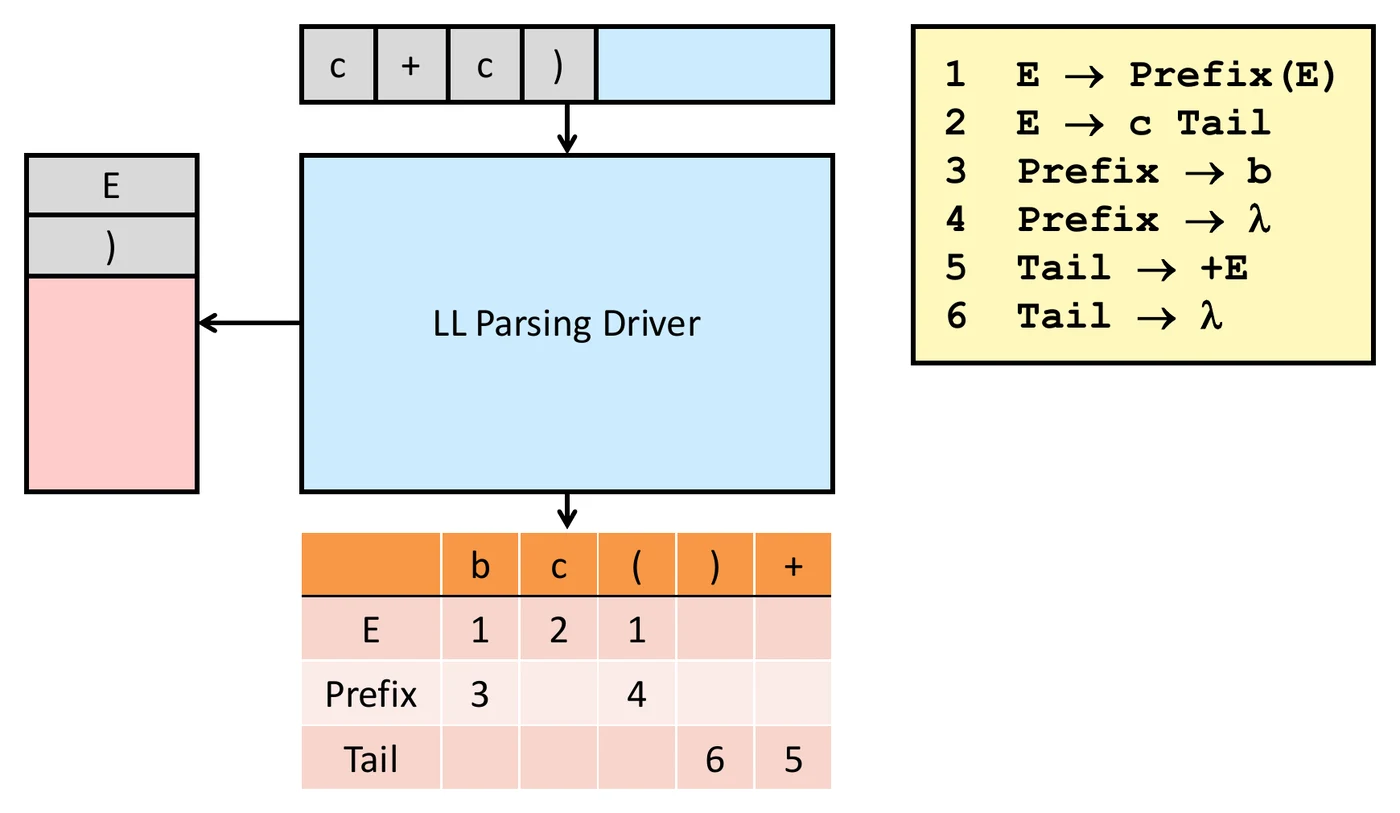
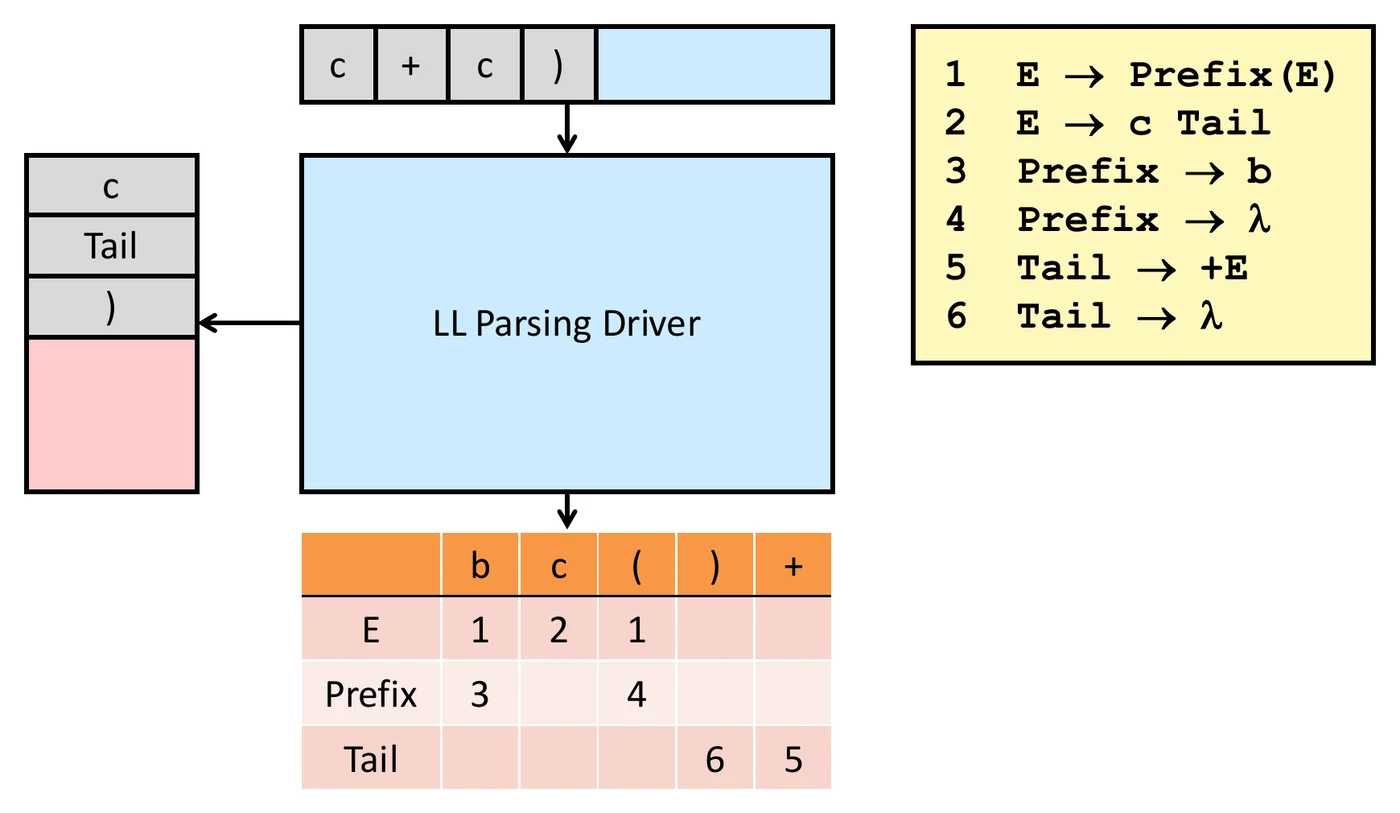
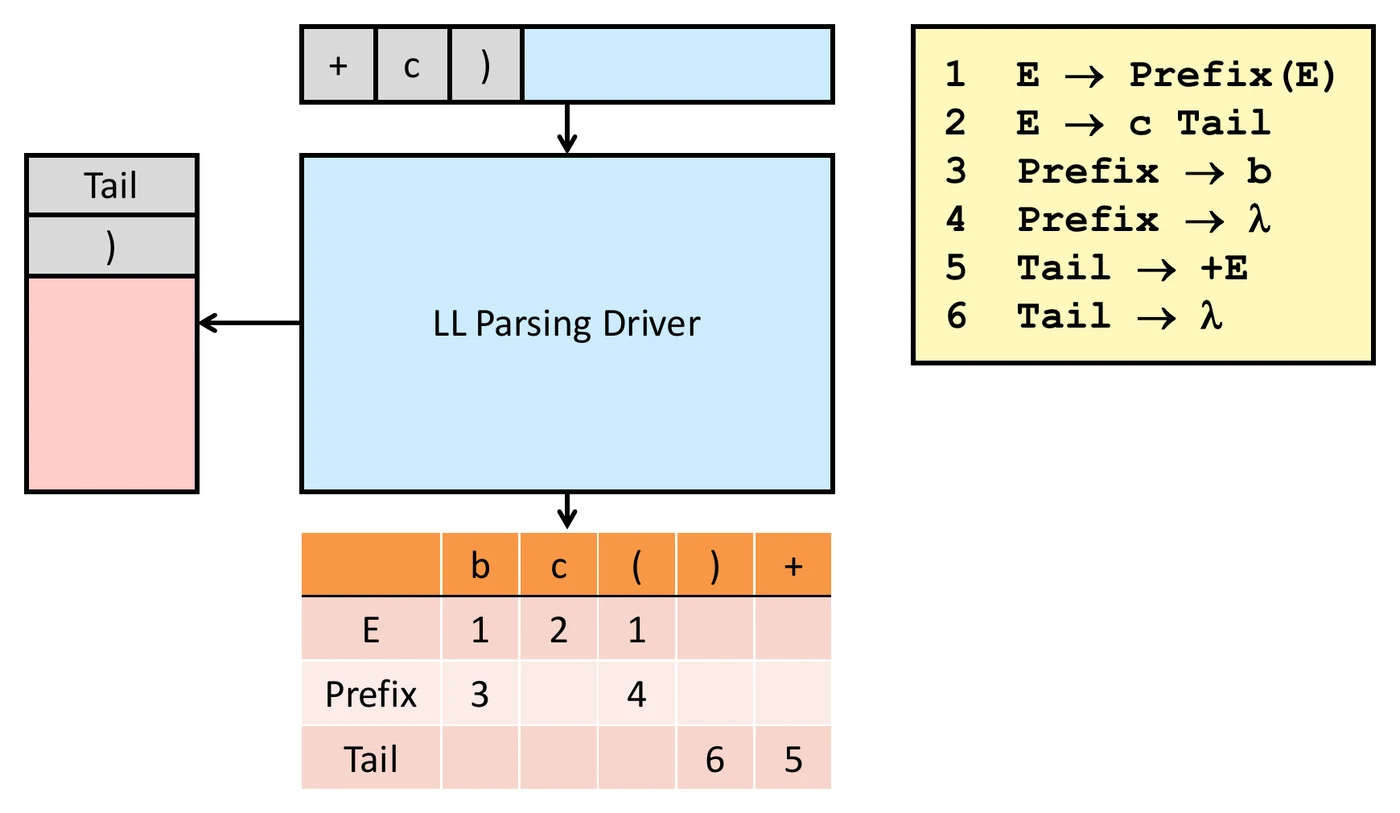
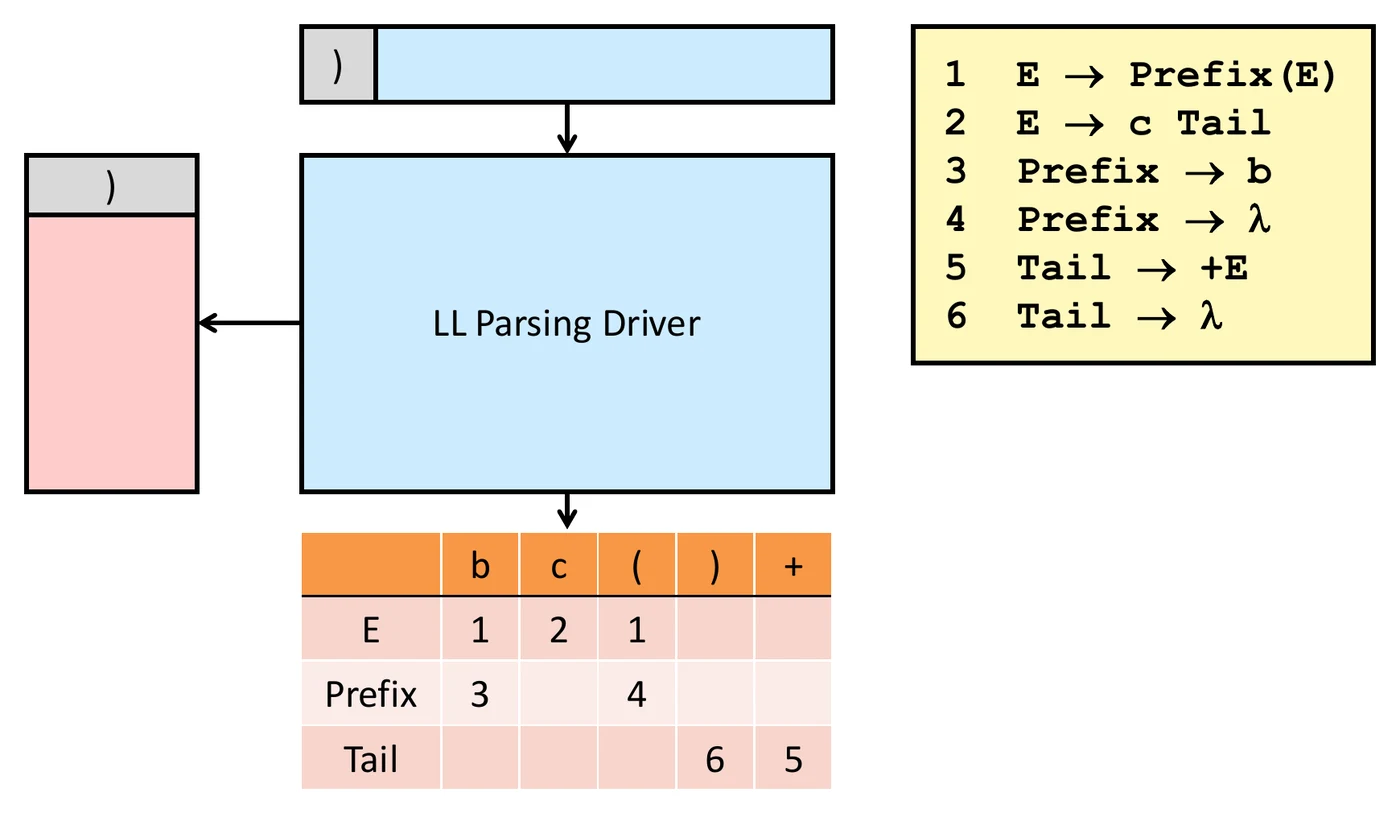
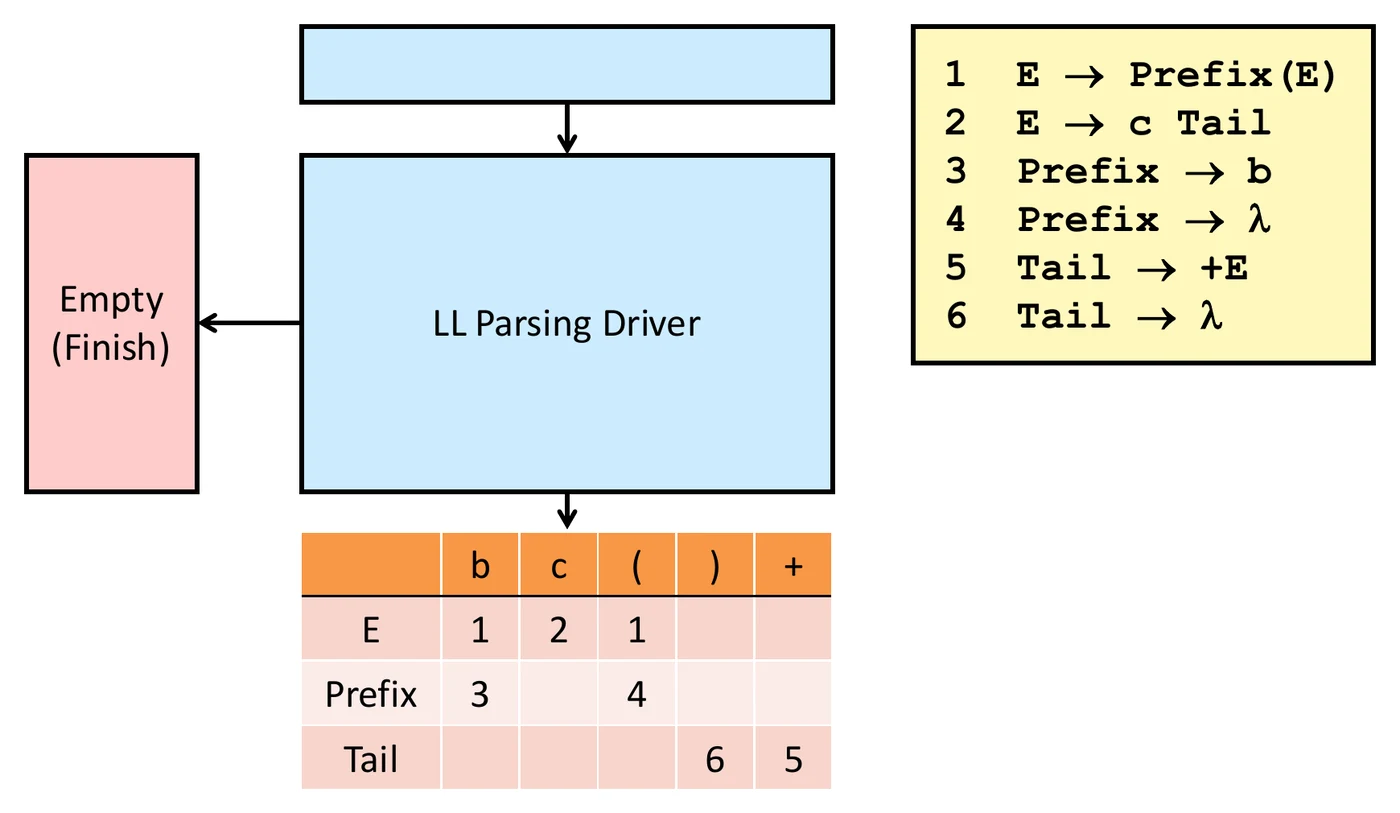
Parser 裡面也有一個 state machine,等等會說怎麼來的
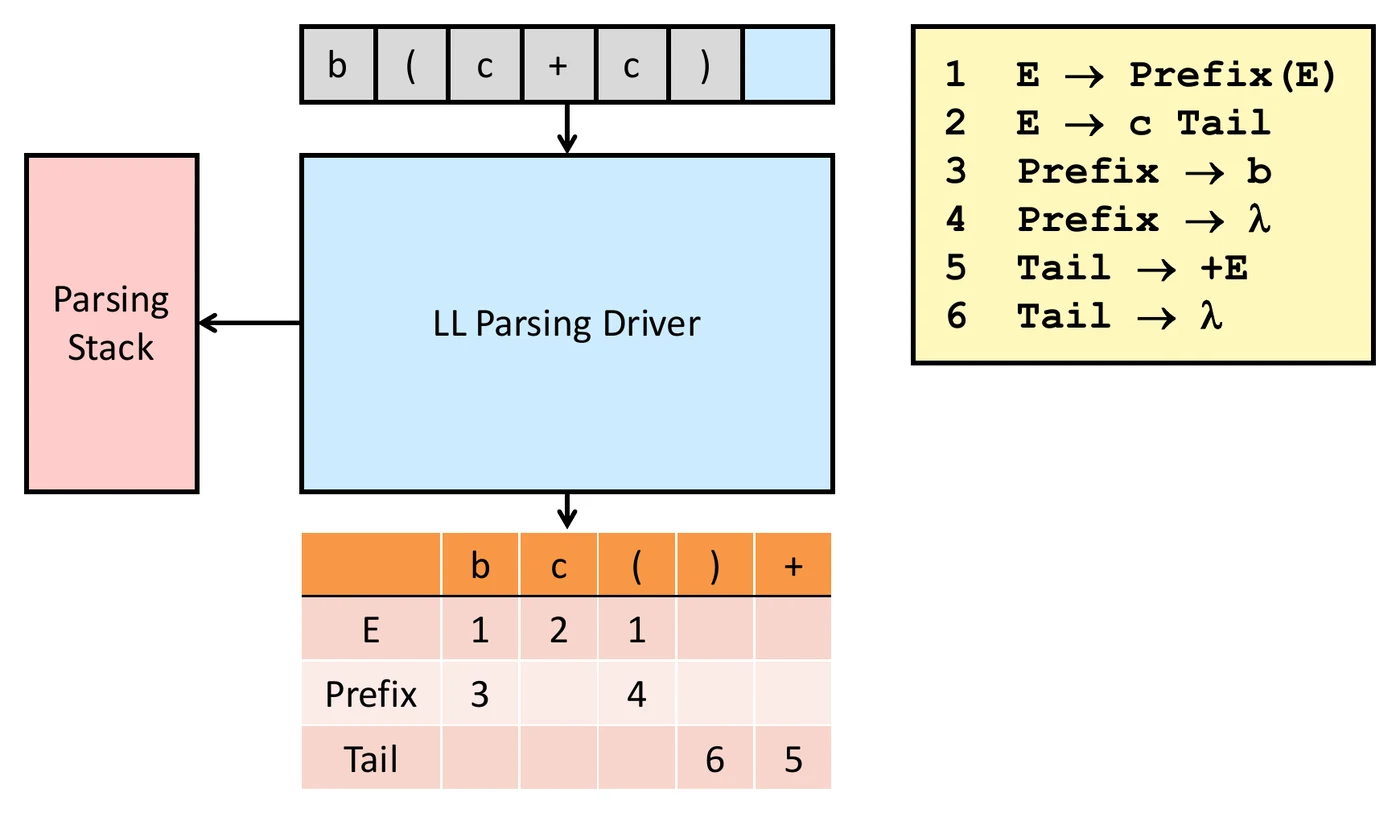
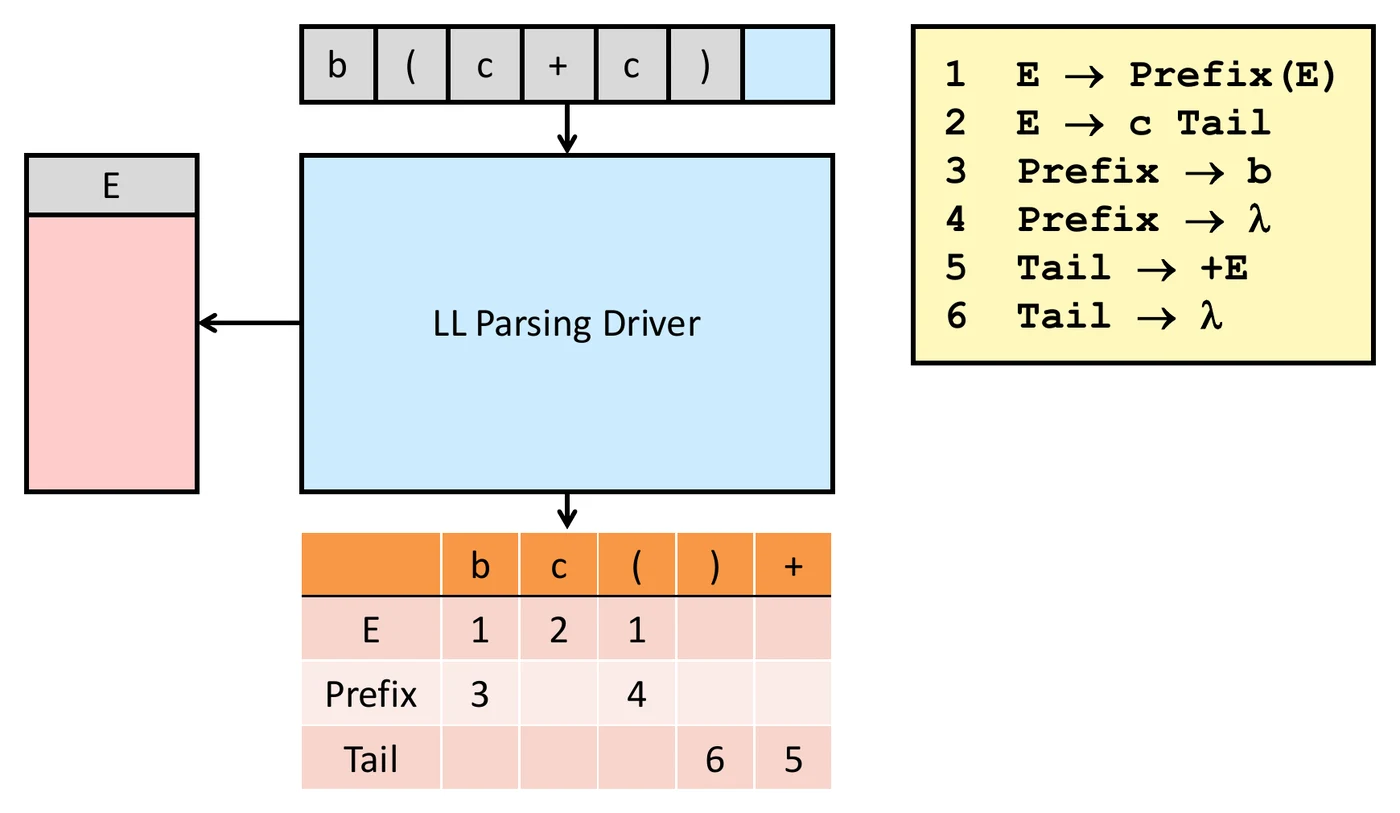
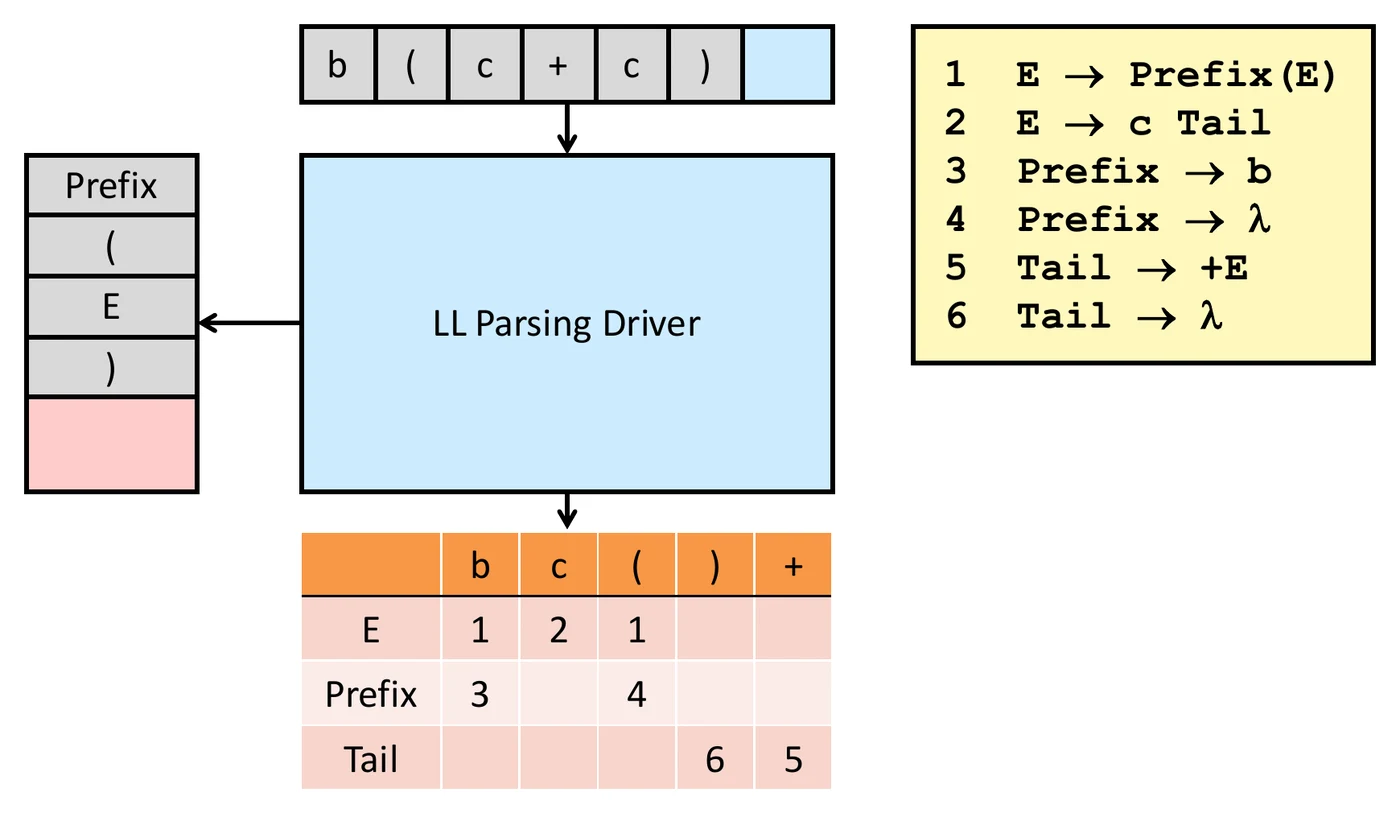
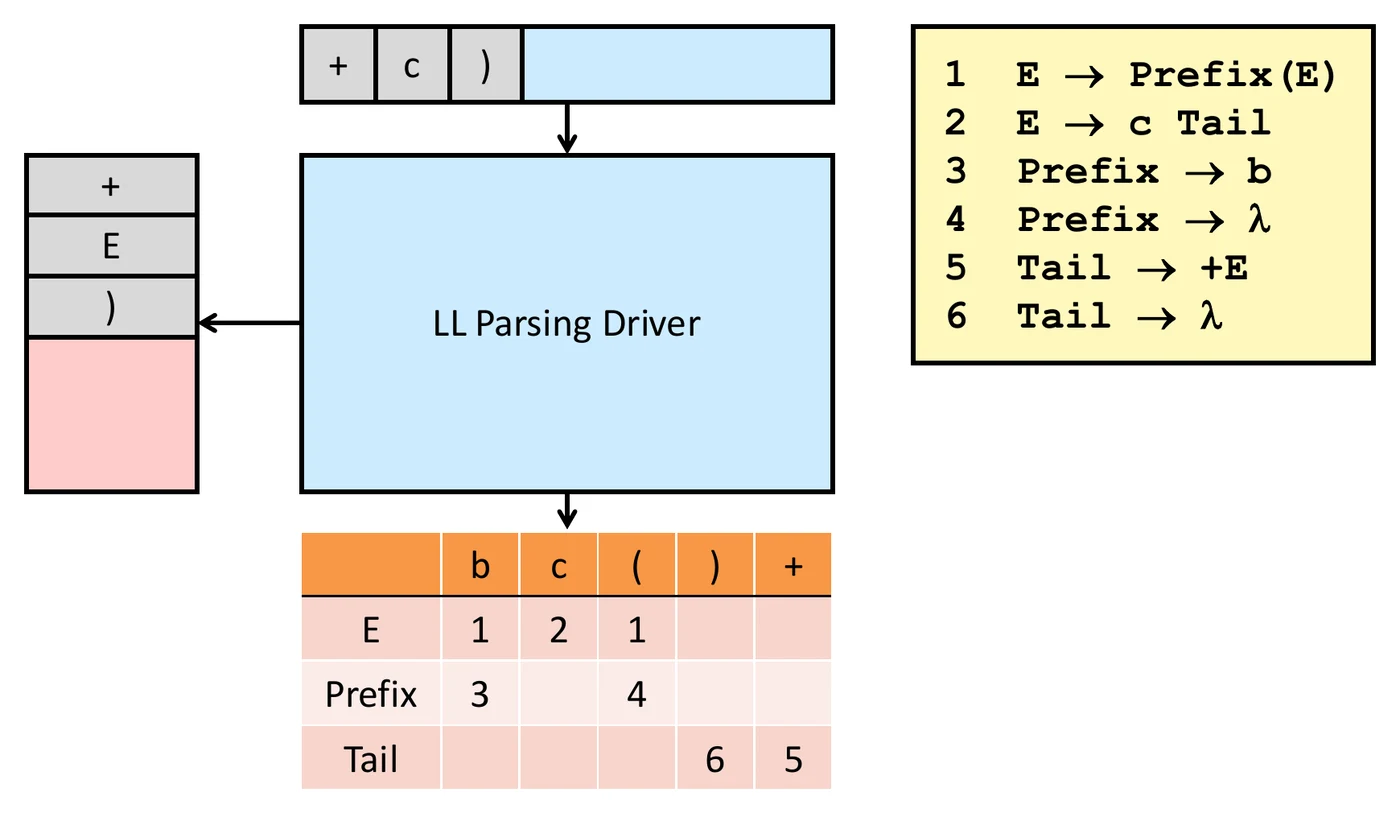
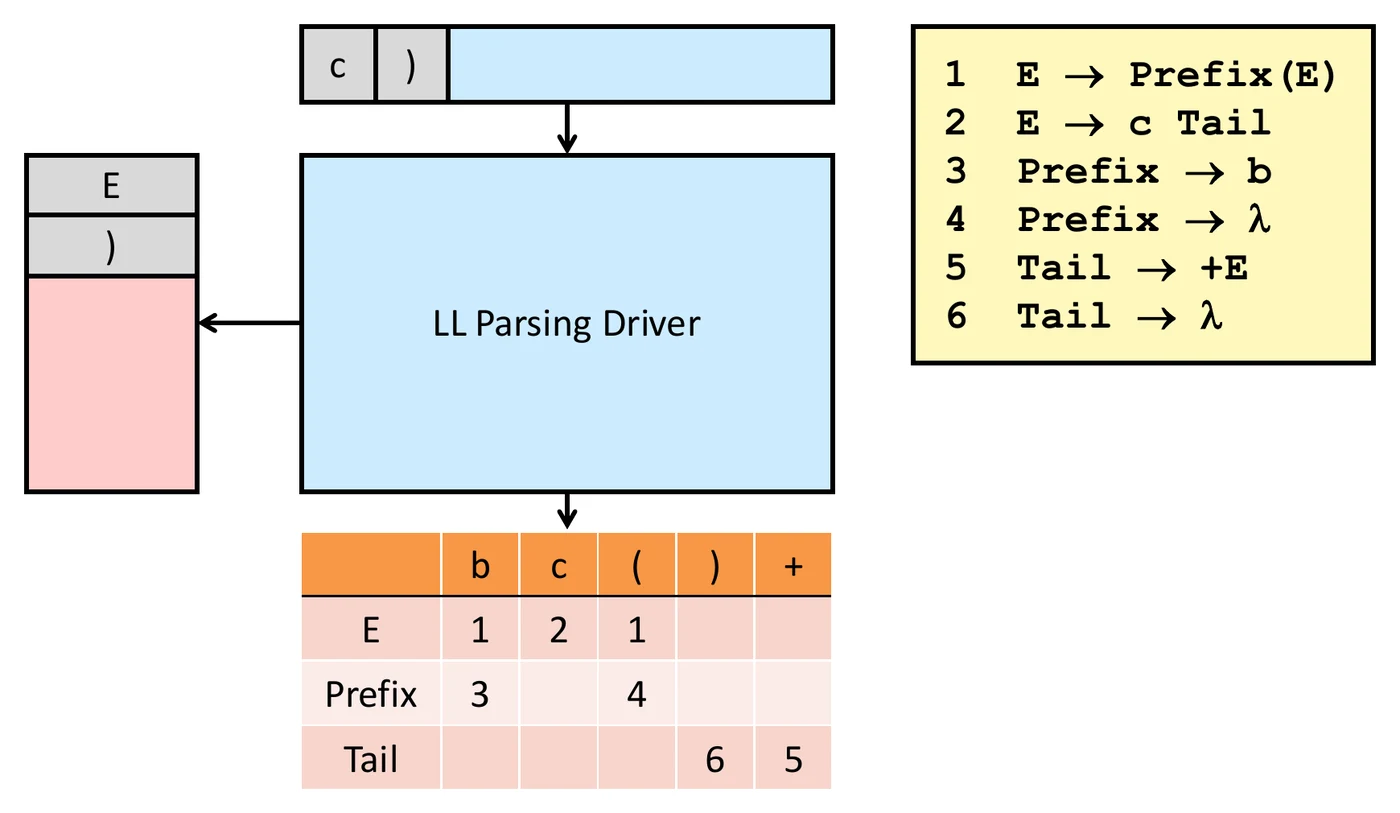
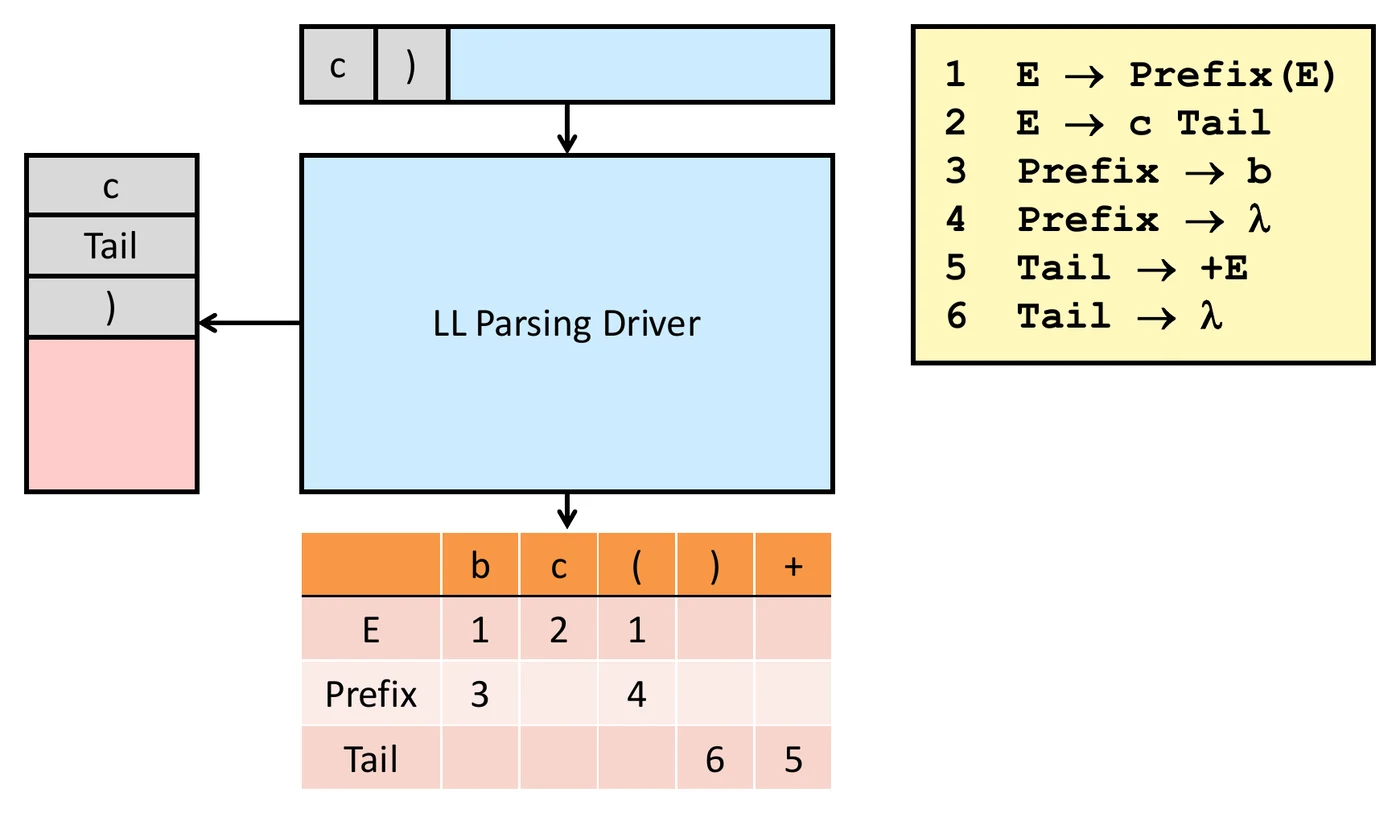
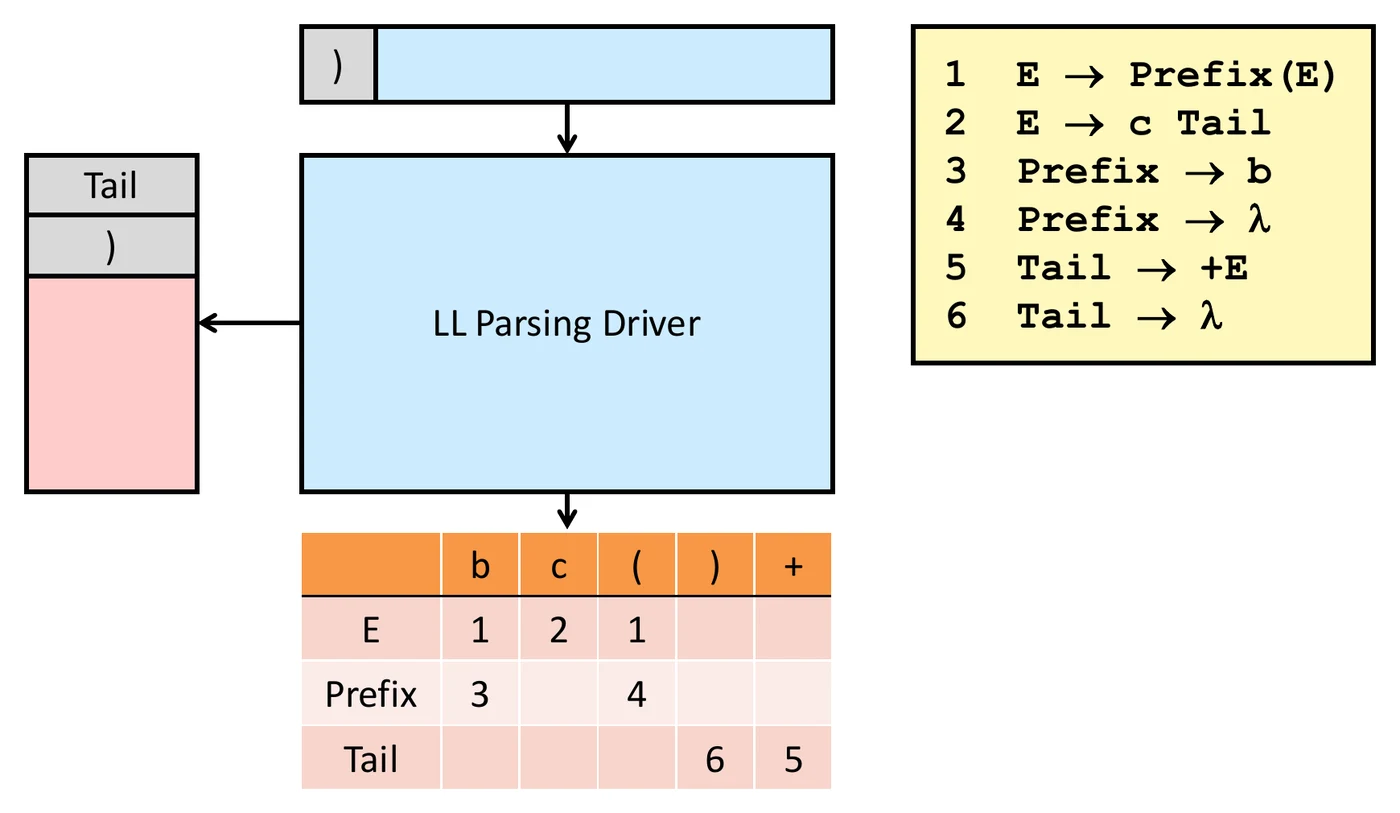
Parse Table#
LL(k) and Predict Function#
我們首先定義一個 Prediction Function
如果我們需要找到一個 的 parsing method 有一個先決條件就是,對於同一個 Symbol 的所有 rule 的 Predict set 一定要是 disjoint 的
以此類推我們可以知道想找到 我們就需要 function, 就是我們的 FIRST set, FOLLOW set 要往後看幾個 token
LL(1) Parse Table#
我們現在來看看 parse table,首先我們討論一下定義
- if
- otherwise
如果發現不是 disjoint 的話,我們填表就會發現某個 entry 裡面有不止一個 rule 可以被放進來,如果是 disjoint 的話,那他就是
Trade-off in Parse Table Implementation#
Similar to Scanner,Parser 也有兩種 Implementation:
- Built-in (Hardwired Parser)
- 將 Parsing Table 中的 parsing decisions 直接 hardwire 到程式碼中
- 例如 Recursive Descent Parser,透過不同的 procedures 和條件判斷來決定使用哪個 production
- Table-driven Parser
- 將 parsing decisions 儲存在 Parsing Table 中
- Parser 根據目前的 Stack Top 和 Lookahead Token 查表,決定下一步使用哪個 production
Hardwire 意思是寫死在程式裡
Parsing Driver#
Built-in Driver#
這是一個基礎的 Built-in Parsing Driver 的一部分,每個不同的 production finding 都有被定義在 code 裡面,我們用這個東西來決定 procedure
procedure A(ts)
    lookahead ← ts.PEEK()
    if lookahead ∈ Predict(p_1) then
        /* Parse using production p_1. */
    else if lookahead ∈ Predict(p_2) then
        /* Parse using production p_2. */
    ...
    else if lookahead ∈ Predict(p_n) then
        /* Parse using production p_n. */
    else
        /* Report a syntax error. */
    end if
end procedure以上是 pseudo code,實際寫出來會像這樣 ↗
Table-Driven Driver#
在 的 language 中,我們可以讓 driver 跟 table 協作,這樣寫出來的 code
- Smaller Code Size
- Recursive Descent Parser 通常每個 Nonterminal 都需要一個 Procedure
- Table-driven Parser 只需要一個通用的 Driver Program + Parsing Table,可能減少重複的程式碼
- Faster Execution
- Recursive Descent Parser 需要頻繁進行 Function Calls / Returns,產生 Call Stack Overhead
- Table-driven Parser 使用 Explicit Stack,不需要透過遞迴呼叫來處理 Nonterminals,因此在某些實作中可能更快
- Portability
- Table method 很好做 extension
procedure LL_PARSER(ts)
    call PUSH(S)
    accepted ← false
    while not accepted do
        if TOS() ∈ V_t then
            call MATCH(ts, TOS())
            if TOS() = $ then
                accepted ← true
            call POP()
        else
            p ← LLtable[TOS(), ts.PEEK()]
            if p = 0 then
                call ERROR("Syntax error — no production applicable")
            else
                call APPLY(p)
end procedureprocedure APPLY(p: A → X_1 ... X_m)
call POP()
for i = m downto 1 do
call PUSH(X_i)
end procedureAction Symbol of LL(1)#
LL(1) Action Symbols#
Action Symbols 可以加入 Productions 中,讓 Parser 在 Parsing 過程中執行對應的 Semantic Actions,例如 Code Generation
後面會提到 Semantic Actions 是啥,以下是一些例子
- Symbol Table Management:把變數加入 Symbol Table,記錄名稱、型別等資訊
- Type Checking:檢查型別是否相容,例如 int + string 是否合法
- Intermediate Code Generation:產生 Intermediate Representation (IR)
- AST Construction:建立 Abstract Syntax Tree
- Semantic Error Reporting:回報未宣告變數、型別不相容等錯誤
- 遇到 Action Symbol 時,會呼叫對應的 Semantic Routine
- Semantic Routine 不一定需要 Explicit Parameters,所需資料可以透過 Semantic Stack 傳遞
- Semantic Stack 儲存 Semantic Records,與 Parse Stack 不同。
- 在 Table-driven Parser 中,Action Symbols 會被 Push 到 Parse Stack,當它成為 Stack Top 時就執行對應的 Semantic Action。
- Action Symbols 不消耗 Input Tokens
比如說
match(ID);
match(ASSIGN);
exp();
gen_assign();
match(semicolon);Making Grammar LL(1)#
當我們發現一個 Parse table 裡面有兩個 rule (production) 的話
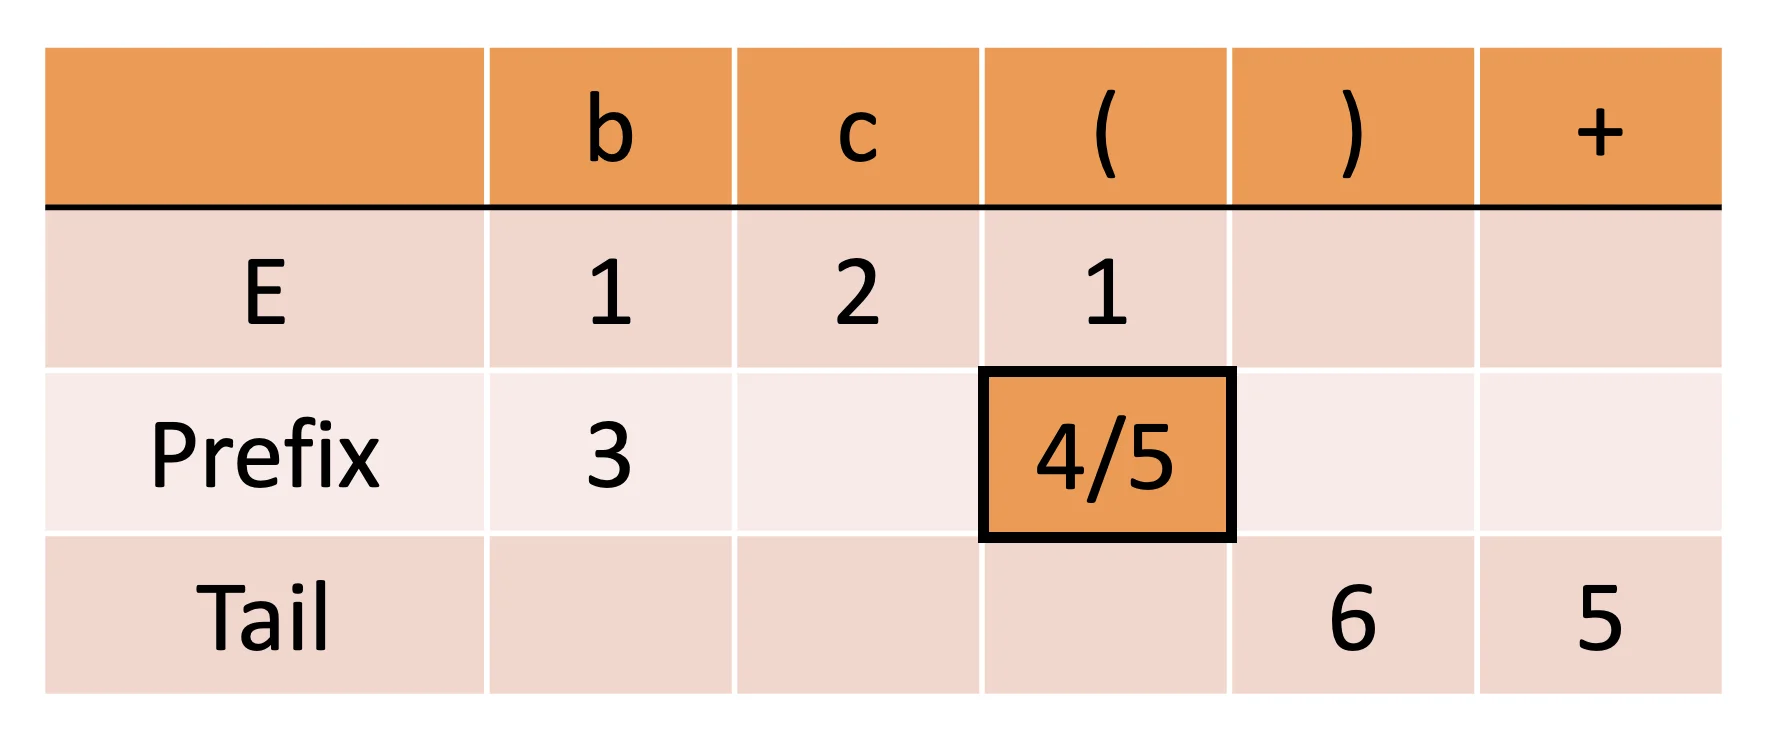
橘色部分,兩個 rule 同時存在在同一個 entry 裡面,這種情況叫做 conflict,造成的原因有很多,根據原因可以用對應的改寫技巧可以讓他變成
Common prefix#
當我們發現有兩個 rule 有共同的 prefix 的時候
用 left factoring 就可以改寫了
Other Case#
還有一些 Case 不行,比如說 left recursion,他會造成 stack 的無窮 push
我們一樣做 left recursion removal